MERR-GAT: Explainable Multimodal Emotion Recognition
WavLM and Compact Conformer audio encoding, BERT/RoBERTa text representations and dual-channel graph attention for multimodal emotion recognition.
- Multimodal inputs
- Audio + text
- Audio encoding and fusion
- Conformer + GAT
- Planned evaluation metrics
- WA / UA / F1
Motivation
I'm studying how audio and text contribute to an emotion prediction. The model combines acoustic and language representations through graph attention, with attribution analysis to inspect the result.
Current architecture
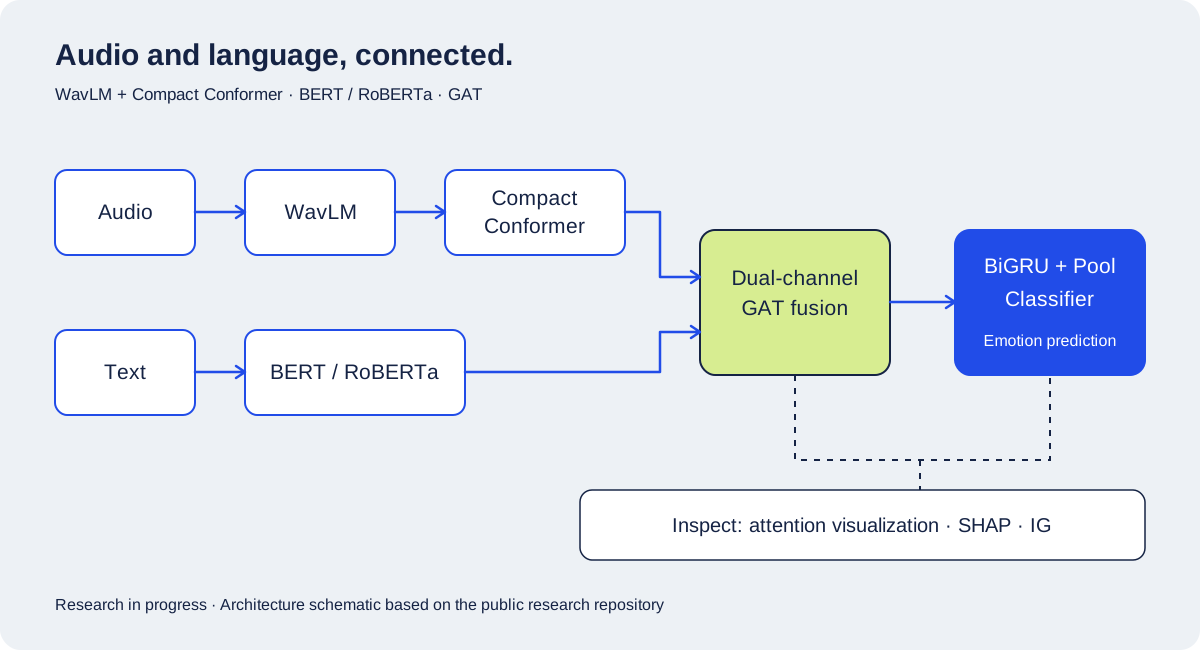
- WavLM-Base provides audio representations.
- A Compact Conformer models the acoustic sequence.
- BERT/RoBERTa provides contextual text representations.
- Dual-channel GAT models intra- and inter-modal relationships.
- BiGRU, pooling and a classifier produce emotion predictions.
The schematic above describes the architecture in the current research repository; it is not a measured model output.
My contribution
Second author and corresponding author. I work on combining the audio and text representations, graph-based fusion, and analysis that makes the predictions easier to inspect.
Explainability
The research uses attention visualization alongside SHAP and Integrated Gradients to investigate modality contributions. Attention is an inspection signal, not a causal explanation on its own.
Evaluation in progress
The repository specifies IEMOCAP, RAVDESS and MELD for evaluation and generalization studies, with Weighted Accuracy, Unweighted Accuracy and Macro-F1 as evaluation metrics. No final accuracy or improvement is claimed here.
What remains
Experiments and attribution analysis are still in progress. Comparisons across datasets need matching evaluation protocols.
Next steps are to complete the experiments, review attribution quality and prepare the research manuscript. The linked repository contains the current research implementation and configuration files.